Best AI models in November 2026: comparison and updates
A business guide to AI models as of November 9, 2026. We compare GPT-6.1, Claude 5.5, Gemini 4 and models with downloadable weights: API prices, benchmarks, availability and the cost of a successfully completed task. Use the comparison to shortlist models for your own business pilot.
Since our September comparison, the market has gained lower-cost models for everyday work, a new generation of Gemini and more options for running models yourself. OpenAI has added GPT-6.1 Sol and Terra, Anthropic has expanded the Claude 5.5 family, and Google has made Gemini 4 Argon available. Alongside capability, it is worth comparing the cost of completing a task and the features you can actually access. The announcements from OpenAI, Anthropic and Google outline the changes.
This November overview covers the state of the market as of November 9, 2026, and the changes since our September comparison. It includes current models, API prices, independent benchmarks and new tools for coding, marketing and business automation.
01Which AI models deserve attention in November
| What you need | Models to shortlist | Why try them? |
|---|---|---|
| Demanding analysis and complex tasks | Claude Opus 5.5, GPT-6 Astra | Strong models for work requiring judgement and multiple steps |
| Everyday coding and business work | GPT-6.1 Sol, Claude Sonnet 5.5 | Both have base API rates of USD 2 / 10 |
| Working with screens, images and text | GPT-6.1 Terra | A focus on visual tasks at USD 1 / 5 |
| Large volumes of straightforward tasks | GPT-6 Luna, Claude Haiku 5.5 | Base rates of USD 0.10 / 0.50 |
| Multimodal work within Google’s ecosystem | Gemini 4 Argon | The publicly available new generation of Gemini |
| Short generated videos | Gemini Omni 1.2 Flash | A November update supporting videos up to 15 seconds long |
This shortlist reflects the positioning and rates published by the providers: Astra, Sol, Terra, Luna, Opus, Sonnet, Haiku, Argon and Omni. Each price pair means input / output per million tokens; we explain the conditions below.
Gemini 4 Carbon belongs on the watchlist for now. Google announced it on October 28, but access is restricted to selected partners. You cannot plan around it in the same way as the publicly available Argon. Google
02What has changed since our September comparison
The most noticeable change is a wider range of choices between the most expensive models and low-cost automation. More products also combine several models, work with applications and continue tasks in the background.
| Date | Event | Practical significance |
|---|---|---|
| Sep 28 | Claude Sonnet 5.5 | A new option for everyday knowledge work and development |
| Sep 29 | GPT-6.1 Sol | A new model for coding and professional work |
| Oct 6 | Mistral Large 4 | Public preview of a new multimodal family |
| Oct 7 | Claude Haiku 5.5 | Lower-cost automation and quick subtasks |
| Oct 12 | Muse Wonder and Wonder Full | Meta adds a more capable model family above Spark |
| Oct 13 | Gemini 4 Argon public launch | The new Gemini generation moves from announcement to an available product |
| Oct 14 | Grok Voice 3.0 | An updated voice model |
| Oct 15 | Muse Spark Open | Meta releases weights under its own licence |
| Oct 17 | DeepSeek-V4.1-Flash-1017 | An updated model with unchanged API prices |
| Oct 20 | Voxtral 3 and Voice Agents | Voxtral 3 in public preview and a new Voice Agents SDK |
| Oct 21 | Claude Duet | A proactive agent in a limited US preview |
| Oct 23 | Kimi K3.1 Pro | A new Moonshot AI model for demanding tasks |
| Oct 26 | GPT-6.1 Terra | Another price tier for visual and office tasks |
| Oct 27 | Artificial Analysis Intelligence Index v5 | A new methodology changes how rankings should be interpreted |
| Oct 28 | Gemini 4 Carbon | A new frontier model with restricted access |
| Oct 28 | AA benchmarks Copilot Fusion | A coding agent combines OpenAI and Anthropic models |
| Oct 29 | Mistral Large 4 open weights | An improved version becomes available for self-hosting |
| Nov 4 | GPT-Image 2.6 Sunburst and Flare | A new generation of image creation and editing tools |
| Nov 5 | Gemini Omni 1.2 Flash | Longer videos and lower generation prices |
| Nov 5 | GPT-6-Cyber | Specialist security work for approved organisations |
Claude Opus 5.5 was released on September 22. Our previous article mentioned it outside the main seven-model selection; in November, it belongs among the leading candidates. Anthropic
03AI models and API pricing at a glance
Prices are in USD per million text tokens with standard processing. These are API rates for your own applications and automations. Monthly ChatGPT, Claude and Gemini subscriptions are billed separately.
| Model | Input | Output | Important condition |
|---|---|---|---|
| GPT-6 Astra | 10 | 50 | Base rate up to 272,000 input tokens |
| GPT-6.1 Sol | 2 | 10 | Base rate up to 272,000 input tokens |
| GPT-6.1 Terra | 1 | 5 | Base rate up to 272,000 input tokens |
| GPT-6 Luna | 0.10 | 0.50 | Base rate up to 272,000 input tokens |
| Claude Opus 5.5 | 4 | 20 | Token prices differ from the cost of a whole task |
| Claude Sonnet 5.5 | 2 | 10 | The same base rate as Sol |
| Claude Haiku 5.5 | 0.10 | 0.50 | Up to 100,000 input tokens; above that, 0.50 / 2.50 |
| Gemini 4 Argon | 2 | 10 | Introductory price until November 30, 2026; then 4 / 20 |
| Muse Wonder | 4 | 20 | API in preview; Wonder Full is a separate offering |
| Muse Spark 1.3 | 1.25 | 4.25 | Standard pricing mode |
| Kimi K3.1 Pro | 2 | 10 | The Highspeed variant costs 4 / 20 |
| Grok 4.7 | 2 | 6 | From 200,000 input tokens, 4 / 12 |
| Mistral Large 4 | 0.70 | 2.10 | Also known as Le Chonk |
| DeepSeek-V4.1-Flash-1017 | 0.30 | 1.20 | Off-peak rates: 0.15 / 0.60 |
| MiMo V2.6 Pro | 0.435 | 0.87 | The regular variant, not Ultraspeed |
| MiMo V2.6 Flash | 0.14 | 0.28 | A smaller model for lower-cost workloads |
For OpenAI, exceeding 272,000 input tokens doubles the input rate and increases the output rate by 50%, across the entire request. A long context therefore does not automatically cost the same per token as a short question. Batch and Flex processing have their own rates. OpenAI pricing
Grok 4.7 and MiMo V2.6 remain relevant models from September. For DeepSeek, distinguish the original version from the 1017 update. Meta has expanded its range: Wonder has an API in preview, while Wonder Full is available to Muse Code subscribers. Wonder’s token rates cannot automatically be applied to Full. Meta, DeepSeek
04The smartest model in the current ranking
For November, we use the Artificial Analysis Intelligence Index v5.0.1. The selected models achieve the following scores in the configurations shown. Carbon has restricted availability, so its first-place result is not a recommendation to deploy it immediately. Current AA leaderboard
| Model and setting | AA v5.0.1 score |
|---|---|
| Gemini 4 Carbon high | 60 |
| Claude Opus 5.5 max | 59 |
| GPT-6 Astra max | 57 |
| GPT-6.1 Sol max | 55 |
| Claude Sonnet 5.5 max | 55 |
| GPT-6.1 Terra max | 51 |
| Gemini 4 Argon high | 50 |
| Muse Wonder Full max | 50 |
| Kimi K3.1 Pro | 46 |
| Muse Wonder max | 44 |
| Claude Haiku 5.5 max | 36 |
| Grok 4.7 xhigh | 35 |
| DeepSeek V4.1 Flash 1017 max | 33 |
| MiMo-V2.6-Pro | 30 |
The table is a selection of models, not a complete ranking of every variant. Scores come from Artificial Analysis, accessed on November 9, 2026.
You cannot directly subtract September’s scores from November’s. Version v5 changed the selection and weighting of tests. November’s v5.0.1 also recalculated CritPt v2 results after changes to the grading system. The difference from Astra’s September score of 53 therefore does not automatically mean the model improved by four points. The index is primarily text-based and in English, so it does not, by itself, identify the best model for Czech either. AA methodology
05Coding and working across an entire repository
When choosing AI for coding, the environment it works in also matters. Access to a terminal, tests, documentation and the right files can affect results just as much as switching models.
Copilot Fusion is one example. It combines OpenAI and Anthropic models and scored 60 on AA’s Coding Agent Index at USD 5.59 per task. Claude Code with Opus 5.5 at max effort scored 62 at USD 11.42. These are costs within that particular benchmark, which evaluates complete agents and their environments. Artificial Analysis benchmark
For everyday development, Sol or Sonnet is a sensible starting point, with Astra or Opus worth trying on the hardest tasks. Validate your choice on your own project: a task should end with a working change that can be tested and reviewed. The number of generated lines tells you little about the quality of the work.
DeepSeek also received a substantial update. For the 1017 version, the provider reports an increase from 31.2% to 42.3% on Terminal-Bench 4.0 and from 74.2% to 77.0% on DeepSWE 1.1. These are its own measurements in specific agent environments, rather than direct proof that it beats every competing model. DeepSeek
Coding Agent Index v2.0 also uses a different mix of tests from the general Intelligence Index, including a different version of FrontierCode. Their scores belong in separate tables. Coding agent methodology and leaderboard
06Agents are moving into everyday work
The new products share several themes: working with applications, retaining longer-term context and continuing work between conversations. For a business, that could mean asking for a regular sales performance review or preparing material from several systems. Our guide to AI agents for business explores the practical possibilities, costs and limitations in more detail.
OpenAI’s autumn updates introduce dots, the shared Space workspace and further tool integrations. The dots rollout is gradual for eligible accounts. Early November brought replies from iOS notifications, while access is expanding into selected enterprise environments. Updates overview, November 2 to 6 updates
Claude Duet monitors connected applications, prepares briefings and works in the background. As of November 9, it is a research preview with a waitlist, starting in the US. Businesses in Czechia should therefore treat it as a direction to watch, rather than a work tool they can already count on accessing. Anthropic
Claude Message threads, now in public beta, is another useful November update for developers building their own agents. The API lets you continue from temporarily retained context and send only new messages. After five minutes of inactivity, the thread expires and the client sends the full history again. November 2 announcement
07What the same volume of tokens costs
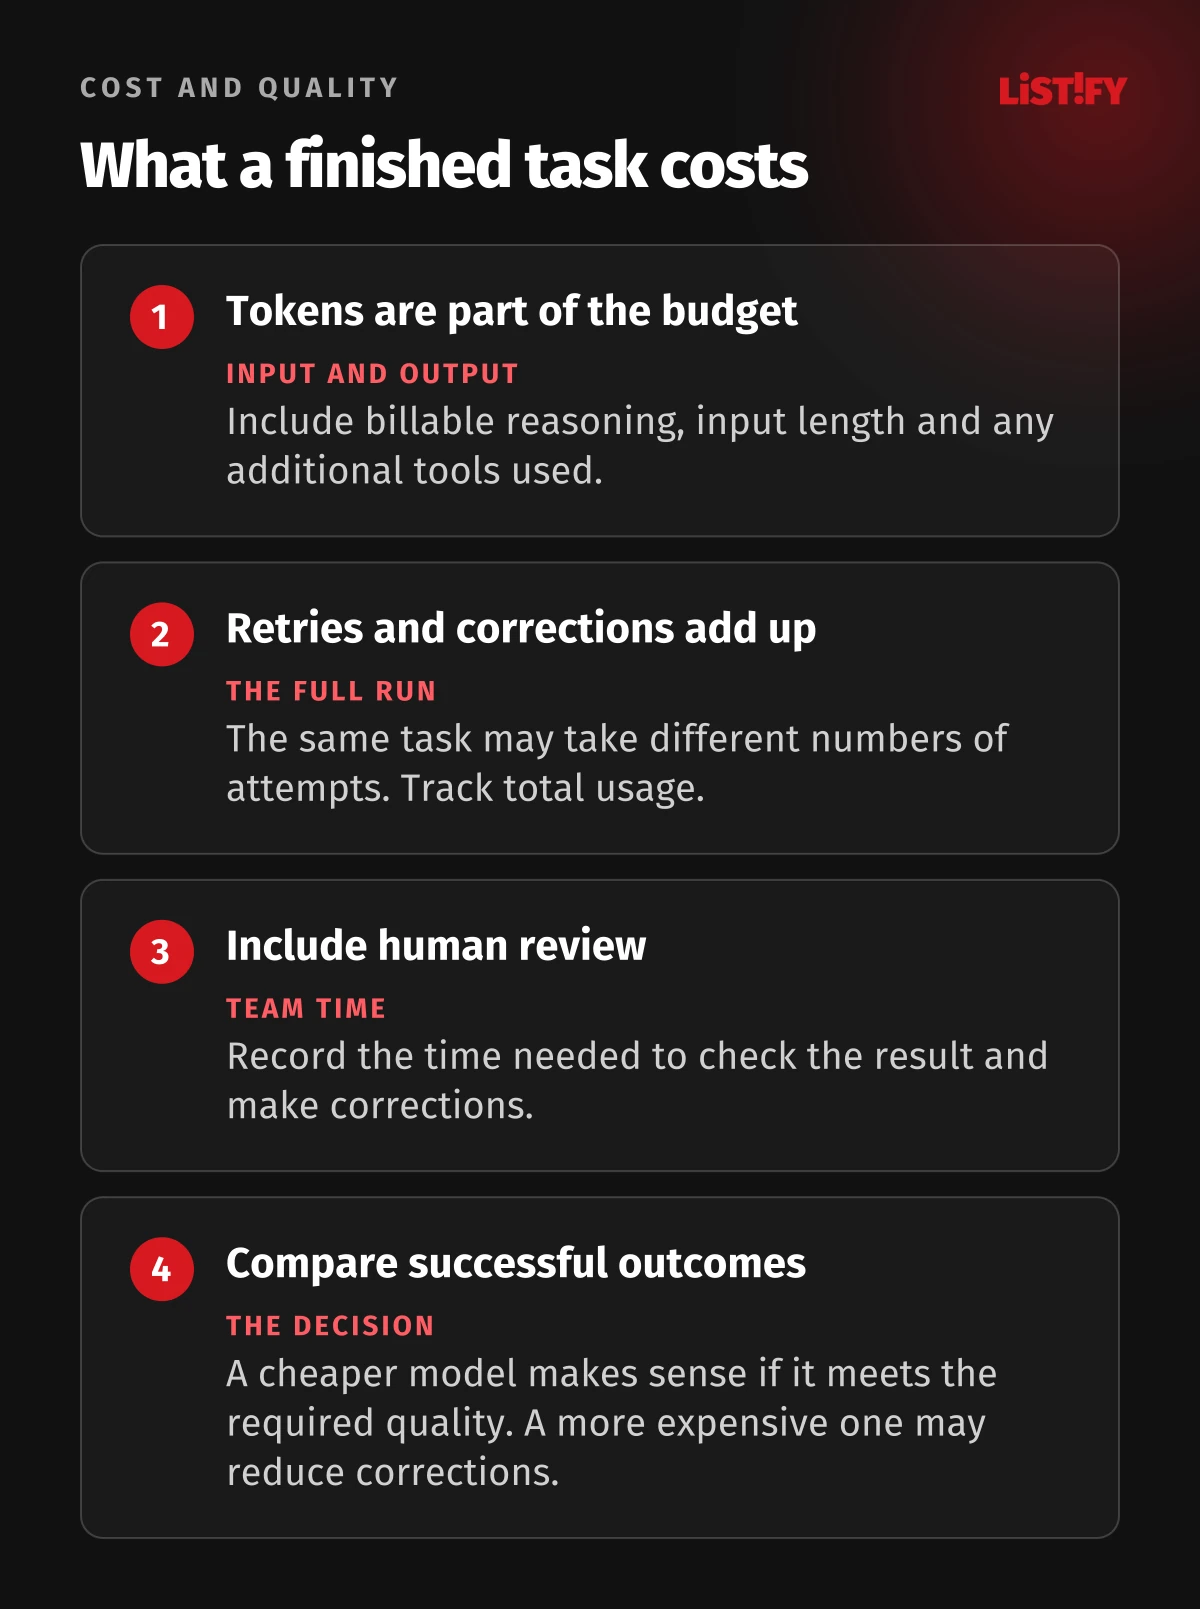
To illustrate the difference, consider 1,000 separate requests, each with 10,000 input tokens and 2,000 billable output tokens. That adds up to 10 million input tokens and 2 million output tokens. We use base rates, without caching, tools or other charges.
| Model | Cost of the example token volume |
|---|---|
| GPT-6 Astra | USD 200 |
| Claude Opus 5.5 | USD 80 |
| GPT-6.1 Sol | USD 40 |
| Claude Sonnet 5.5 | USD 40 |
| Gemini 4 Argon until November 30 | USD 40 |
| GPT-6.1 Terra | USD 20 |
| GPT-6 Luna | USD 2 |
| Claude Haiku 5.5 | USD 2 |
| MiMo V2.6 Flash | USD 1.96 |
This is our own calculation from the rates in the pricing table, not a measurement of equal-quality results. The output volume must include any billable reasoning tokens. A model that needs more attempts or longer answers can consume a different number of tokens to complete the same task.
In your pilot, track the cost of a successfully completed and reviewed task. A low-cost model is worthwhile wherever it meets your quality standard. A more expensive one may be more economical if it substantially reduces the corrections people need to make.
08Context windows and working with documents
Astra, Sol, Terra and Luna have a 1.05-million-token API context window and a maximum output of 128,000 tokens. Individual products may have different default limits; for example, Sol’s documentation lists a standard 500,000-token limit for Codex and ChatGPT Work. Astra, Sol, Terra, Luna
For Gemini 4 Argon, Google specifies a shared one-million-token limit for input and output. Two specifications labelled “one million tokens” may therefore leave different amounts of room for documents and the resulting answer. Google
A large window helps when the model needs to work with several related sources at once. For a business knowledge base, it still pays to select relevant documents and provide their sources. A long input alone does not guarantee that the model will find the right information or notice conflicting versions.
09Images, video and voice
GPT-Image 2.6 Sunburst and Flare expand image generation and editing options. Sunburst supports detailed compositions, edits to marked areas, SVG and animated GIFs. For marketing teams, this offers further ways to produce creative variations and make targeted visual corrections. Sunburst documentation
Gemini Omni 1.2 Flash has supported videos up to 15 seconds long since November 5. Google lists a price of USD 0.07 per second at 720p and supports video editing through follow-up conversation. At that rate, generating one 15-second clip costs USD 1.05; extra attempts or further processing will increase the budget. Google
Genie 4 focuses on interactive simulated worlds with native audio. Google introduced it on October 27 as a research preview for trusted testers. It is a development that could influence prototyping and simulation, but it is not yet an everyday replacement for an advertising video tool. Google DeepMind
Voice applications have gained Grok Voice 3.0 and Mistral’s Voxtral 3 with Voice Agents. Since November 2, OpenAI has made outbound SIP calling through the Live API available to all organisations. When testing a customer service line, assess how clearly it handles Czech, its responsiveness, interruptions and handover to a person. xAI, Mistral, OpenAI
10Open weights and running models yourself
There is also a wider choice of models with downloadable weights than in September. Alongside DeepSeek and MiMo, important options have arrived from Meta, Moonshot AI and Mistral. Their licences differ, however.
| Model | Status as of November 9 | Licence |
|---|---|---|
| DeepSeek-V4.1-Flash-1017 | Weights available | MIT |
| MiMo V2.6 Pro | Weights available | MIT |
| Muse Spark Open | Weights available | Custom Muse Model License |
| Kimi K3.1 Pro | Weights available | Custom Kimi K3.1-Pro License |
| Mistral Large 4 | Weights available since October 29 | Mistral Ecosystem Open-Weight License |
| Inkling 2 Small | Available through Tinker; weight release announced | Apache 2.0 planned for the weights |
As of this overview, Kimi’s actual model files can be downloaded. For Inkling, the November 5 announcement promises to release weights only after external safety testing. These situations have very different implications when planning your own deployment. Kimi repository, Thinking Machines
Open weights do not necessarily mean a small model. Muse Spark Open has 816 billion parameters in total, with 42 billion active per token. Its model card specifies at least 700 GB of graphics memory for NVFP4. This belongs in infrastructure planning, rather than on a list of simple installations for an ordinary laptop. Meta model card
Running a model yourself gives you control over its location and data flows. It also brings responsibility for updates, access controls, capacity and operational monitoring. For custom licences, check the terms that apply to your intended use, especially if you want to offer the model to other customers as a service.
11Security and business data
For business deployments, distinguish between the model, the API provider and the application you use. Data retention, connector permissions and audit capabilities can differ even when the same model runs underneath.
On November 5, Anthropic introduced further Claude Enterprise security features, including a security centre, centralised controls and inference hooks to check prompts and tool calls before execution. Some features are in beta. For a larger team, access to these controls may matter more than a small benchmark difference. Anthropic
The specialist GPT-6-Cyber is intended for investigating vulnerabilities, reproducing them in authorised testing environments and verifying fixes. It requires Daybreak Red access and organisation approval. An ordinary subscription therefore does not, by itself, grant access. OpenAI documentation
Before connecting an agent to your CRM or accounting system, define what it may read, what it may change and which steps it must present to a person. A pilot using a copy of your data can reveal problems before they affect customers or business operations.
12Science and reasoning need precise benchmark names
In AA’s current comparison, Gemini 4 Carbon at high effort scores 69.1% on HLE-Diamond, while Claude Opus 5.5 at max scores 67.9%. On Terminal-Bench-Science 0.1, their results are 64.8% and 59.0%. These figures describe specific task sets; they cannot be substituted for results from older or differently configured versions of Humanity’s Last Exam. AA comparison
For business analytics, define your own test just as precisely. A model should not only reach an answer, but also use spreadsheets correctly, distinguish assumptions from facts and make calculations easy to check. An answer that sounds convincing may be less useful for a decision than a shorter response with verifiable supporting evidence.
13What the first days of November brought
Alongside image models, video and security tools, smaller updates have also arrived that can affect everyday operations:
- Claude Marketplace added more partner agents and products on November 4. They cover security, development, creative work and productivity. Announcement
- Personal Finance in Claude entered beta in the US on November 5. It connects personal financial accounts; readers in Czechia cannot yet assume it will support their bank. Announcement
- Claude Enterprise added project tags in beta on November 6. They let teams track most costs by project code, client or engagement. Release notes
- Artificial Analysis introduced Decision Index v2 on November 8. It covers decision tasks, document work and confidence calibration, offering another way to assess AI’s usefulness in automation. Announcement
- Thinking Machines launched Inkling 2 Small in Tinker on November 5. The new model supports text and images; the announced weight release is due to follow further testing. Announcement
- Mistral expanded Studio on November 5. The update brings together agents, workflows and applications using Le Chonk. Announcement
- Meta introduced specialised models for Muse and Meta AI on November 6. They build on Wonder and bring Active Memory and Active Focus capabilities. This is more than a rename of the general-purpose API model. Announcement
14Which AI model should your business choose?
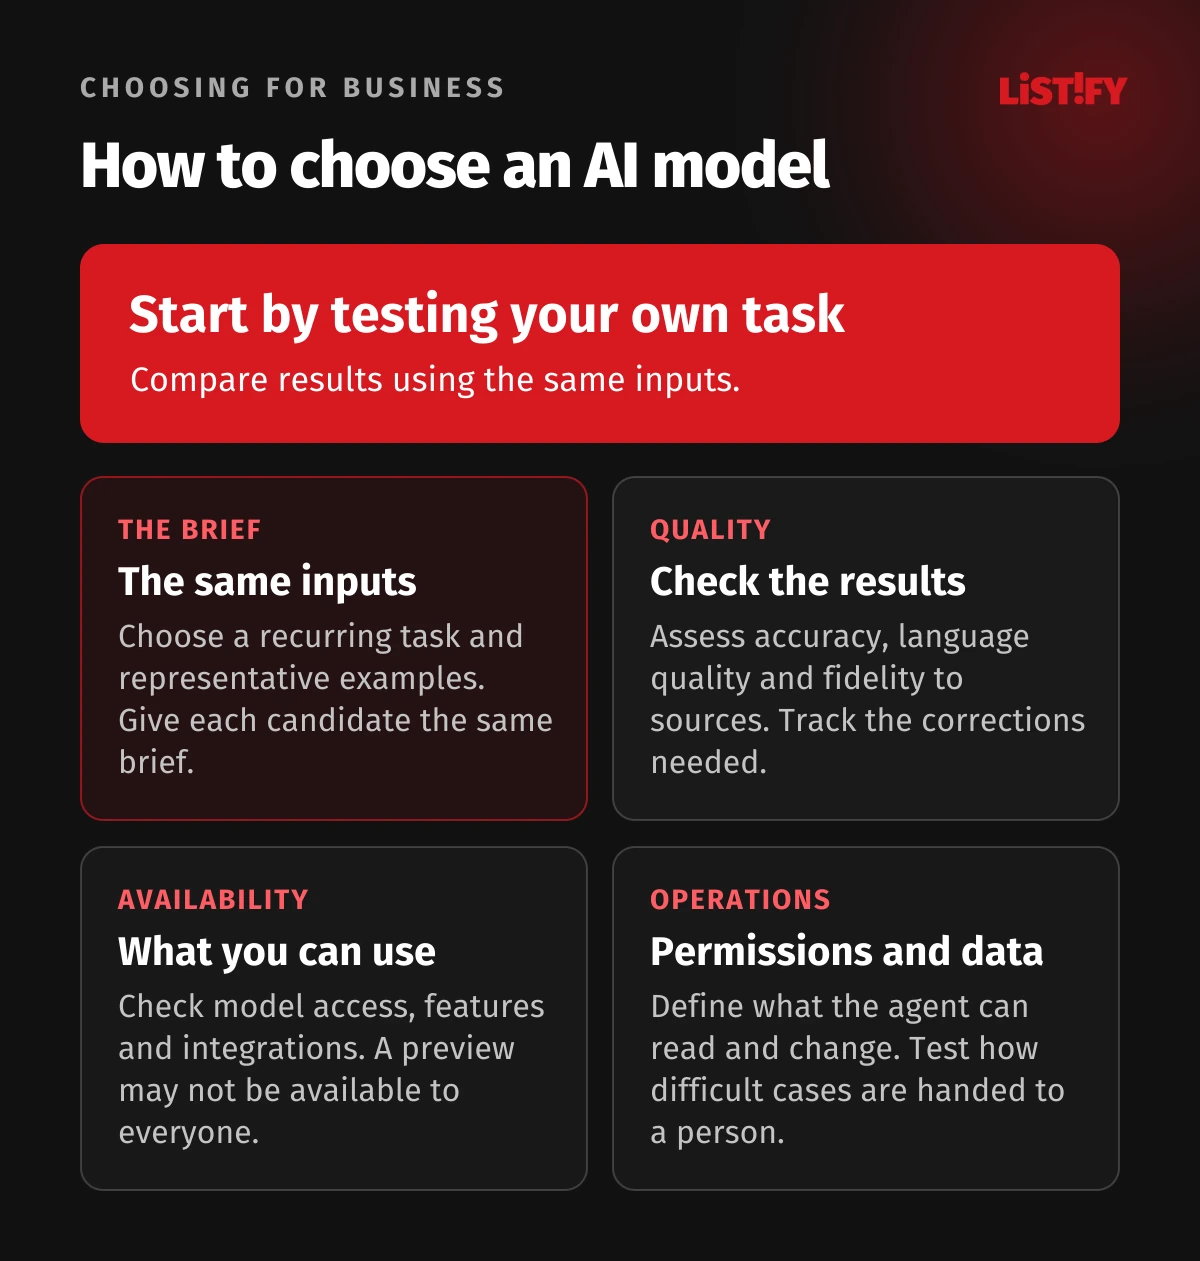
Start with two or three recurring tasks where you know what a good result looks like. Give several candidates the same material and instructions. Assess correctness, time, the number of corrections and total cost.
| Type of work | What we would try first | What to measure |
|---|---|---|
| Classifying enquiries and extracting data | Luna and Haiku | Misclassified cases and accuracy across all required fields |
| Proposals and work with visual material | Terra, Sonnet and Argon | Faithfulness to sources, Czech-language quality and the finished document |
| Everyday application development | Sol and Sonnet | Tests passed, regressions and time spent reviewing changes |
| Demanding refactoring or analytical problems | Opus and Astra | Successful completion, a traceable process and the number of interventions |
| A long-running agent connected to business systems | The best model from your own pilot | Reliability across multiple steps, permissions and the cost of the entire run |
For work in Czech, include real emails, specialist texts and customer queries. A general international leaderboard may not reflect the terminology or style you need.
A practical architecture can use a cheaper model for routine work and a stronger one for difficult cases. Handover rules should reflect observed errors and the nature of the task. A model’s own claim that it is confident is not enough to make a safe decision. Our AI implementation service can help design your pilot and connect it to your systems.
15Frequently asked questions
Should we switch providers as soon as a new model arrives?
First compare results on your own tasks. A switch is worthwhile if it delivers better quality, a lower cost per successful task or a feature your current solution needs. Include the work involved in changing the integration.
Which models are the cheapest?
It depends on the balance of input and output. At base rates, Luna and Haiku have cheaper input than MiMo V2.6 Flash, while MiMo has cheaper output. That is why MiMo Flash costs USD 1.96 for our example volume, compared with USD 2 for the other two. Real costs also depend on reasoning length and repeated attempts.
Is Gemini 4 Carbon available to everyone?
As of November 9, it is not generally available to the public. Google describes limited testing with selected partners. Argon is the relevant option for everyday deployment of the new Gemini generation. Google
Do open weights mean free operation?
No. You still need hardware or rented compute, deployment, monitoring and maintenance. Assess the licence separately too. Downloadable weights and unrestricted commercial use are different things.
What should we check before the end of November?
Pay particular attention to introductory prices and access to preview features. Google states that Argon’s introductory rate ends on November 30, 2026. When planning subsequent usage, budget for the announced standard price. Google
16What the November comparison means in practice
Choosing AI now means choosing among more price tiers and specialisms. The useful question is: which model can do our work to the standard we need, at an acceptable cost, with the integrations available to us?
For a business, a short pilot is a sensible first step. Choose a specific process, prepare representative tasks and compare several models. Use the results to decide where low-cost automation is enough and where a more capable model or human review adds value.
Want to bring AI into your business? We can identify where AI makes sense in your operations, select suitable models and connect them to the systems you already use.